Free labs, articles & videos
Learn to build AI you can actually measure.
I'm Slav Kurochkin, an engineer focused on AI quality. I share what I've learned from 10+ years of building test infrastructure and quality systems, and from evaluating LLM apps and AI agents: hands-on labs, practical articles, and videos.
$ evals run --suite support-agent --baseline main
  task_success     0.912 → 0.934   +2.2pp (95% CI ±1.1)
  tool_call_valid  0.981 → 0.987   +0.6pp
  judge_agreement  κ = 0.81 vs human labels
  p95_latency      2.4s  → 2.9s    +0.5s ⚠ within budget
✓ gate passed: improvement is significant, no regressions
What you'll learn
The quality stack for AI in production
Evals tell you if a change made things better. Observability tells you what happens in production. Deterministic tests cover everything around the model. You need all three.
Eval datasets & LLM judges
Datasets sized so a 2% improvement is real, and judges calibrated against human labels.
Agent evaluation
Grade trajectories and tool calls, not just final answers.
AI observability
Tracing, dashboards, and alerts for quality, cost, latency, and drift in production.
Deterministic test automation
Repeatable UI, API, and contract tests for everything around the model.
CI quality gates & infrastructure
Pipelines and eval infrastructure that block regressions without blocking real improvements.
Voice & speech AI
STT, TTS, and voice agents: WER, latency, and streaming quality.
Learn
Hands-on learning tracks
Practice-first labs. Build a system, break it on purpose, and measure what changed.
25 episodes · Beginner → Intermediate
AI Engineering: Hands-on
Prompts, memory, context, search, RAG, evals, reasoning, agents and multi-agent teams, measured on recorded runs.
7 episodes · Intermediate
MCP Servers: Build, Secure, Evaluate
Connect a real MCP server, prove tenant boundaries, and test tool use before release.
10 episodes · Intermediate
Voice AI Evaluation
Speech-to-text, text-to-speech, and voice agents.
14 labs · Beginner → Intermediate
LLM Evals: Foundations
How many evals are enough, and how to trust an LLM judge.
9 labs · Intermediate
Agent Evaluation
Measure what agents do, not just what they say.
5 labs · Advanced
Support Agent: Full Lifecycle
One real agent, taken from spec to production evals.
YouTube
Latest videos
Hands-on episodes on testing and evaluating real AI systems.

Oct 26, 2026
My Small Model Copied the Big Model's Mistakes: Distillation, DPO and RFT, Measured
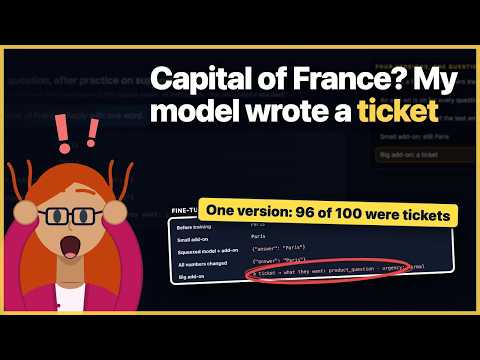
Oct 26, 2026
I Asked My Fine-Tuned Model the Capital of France. It Wrote a Support Ticket: What Training Broke

Oct 26, 2026
I Fine-Tuned a 0.6B Model on My Laptop. It Matched GPT-5.4-mini on One Job: LoRA, Measured
Writing
From the blog
Oct 10, 2026 · 2 min read
How Many Evals Are Enough?
Your eval score went from 84% to 86%. Is that a real improvement, or noise? A practical guide to sizing eval sets.
Oct 3, 2026 · 2 min read
Your LLM Judge Is a Measuring Instrument. Calibrate It.
LLM-as-judge is only as trustworthy as its agreement with humans. How to measure that agreement, and what to do when it's low.
Jun 11, 2026 · 1 min read
What if your software could explain itself? AI agent mapping user journey to a software architecture
A video walkthrough of an AI agent that maps a user journey onto the software architecture behind it.
Learning something useful?
New labs, articles, and videos on evaluating and testing AI systems come out regularly. Follow along so you don't miss the next one.